Audio-Video LLM Token Compression Diagram
Overview
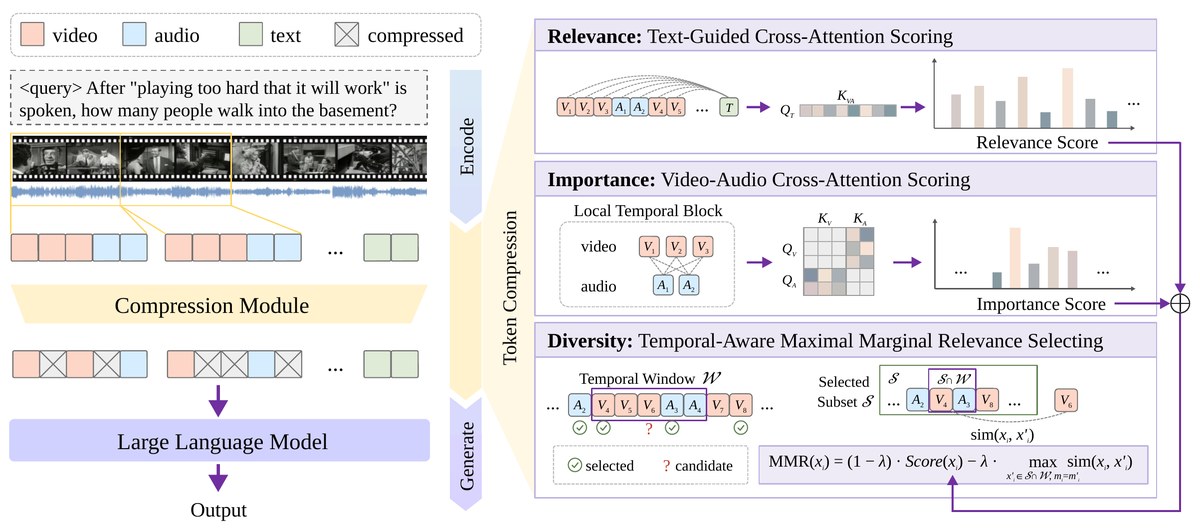
A left main pipeline plus three right-hand scoring panels for compressing audio-video tokens before an omni-modal LLM. It is an editable PowerPoint diagram adapted from the original paper figure under CC BY 4.0.
What the diagram shows
Left: query, video film strip and audio waveform → interleaved video/audio/text tokens → compression module → compressed tokens → large language model. Right: Relevance (text-guided cross-attention scoring), Importance (video-audio cross-attention in a local temporal block) and Diversity (temporal-aware maximal marginal relevance, MMR) combined with ⊕ into the final selection. Every box, arrow, label and math term is a native shape you can recolor, resize and relabel for your own slides, posters or papers.
File format
The download contains .pptx (1 slide, 15.52 × 6.88 in; opens in PowerPoint, Keynote, WPS and LibreOffice Impress; Google Slides works too, but complex freeforms may shift slightly), .svg and .drawio. Includes preview.png (full resolution) and a 1200 px web preview.
Shapes and editing
The file has 237 native editable shapes: 125 auto-shapes, 48 text boxes, 31 freeforms, 33 lines/connectors. 2 embedded images (see below). You can edit all text and formulas (Q_T, K_VA, Q_V, K_A, MMR(x_i), 𝒮, 𝒲), every token box including the crossed "compressed" tokens, attention vectors and matrices, bar charts with axes, the Encode / Compression / Generate chevrons, dashed arcs and the purple routing lines.
Embedded images and fonts
2 items are embedded images: the video film strip and the audio waveform. Text uses Times New Roman, which is preinstalled on Windows and macOS (LibreOffice uses the metric-compatible Liberation Serif). A few calligraphic math letters (such as 𝒩, ℰ, 𝒮) use Cambria Math, which ships with Microsoft Office; other apps substitute a math font. Sub- and superscripts are real formatted text runs, not equation objects. The SVG keeps text as text; the draw.io file is a shape-by-shape conversion and may need small nudges. This is a faithful redraw for reuse, not the authors' original source file.
Source & license Adapted from Figure 2 of AVOC: Enhancing Hour-Level Audio-Video Understanding in Omni-Modal LLMs via Retrieval-Inspired Token Compression by Yijing Chen, Wenhui Tan, Xiaoyi Yu, Yuyue Wang, Xin Cheng, Kaisi Guan, Hao Jiang, Xiangyang Li, Guojie Zhu, Ruihua Song (arXiv:2606.24286, https://arxiv.org/abs/2606.24286; code: https://github.com/YJCX330/AVOC). Licensed under CC BY 4.0 (https://creativecommons.org/licenses/by/4.0/). Redrawn as editable shapes; changes made by 叫我Alonzo就好了/alonzolab. Not endorsed by the original authors. Attribution to the original paper is required when you publish or share the figure; the exact credit line is in LICENSE-ATTRIBUTION.txt inside each download.