Grouped Image Flow-Matching Transformer Diagram
Overview
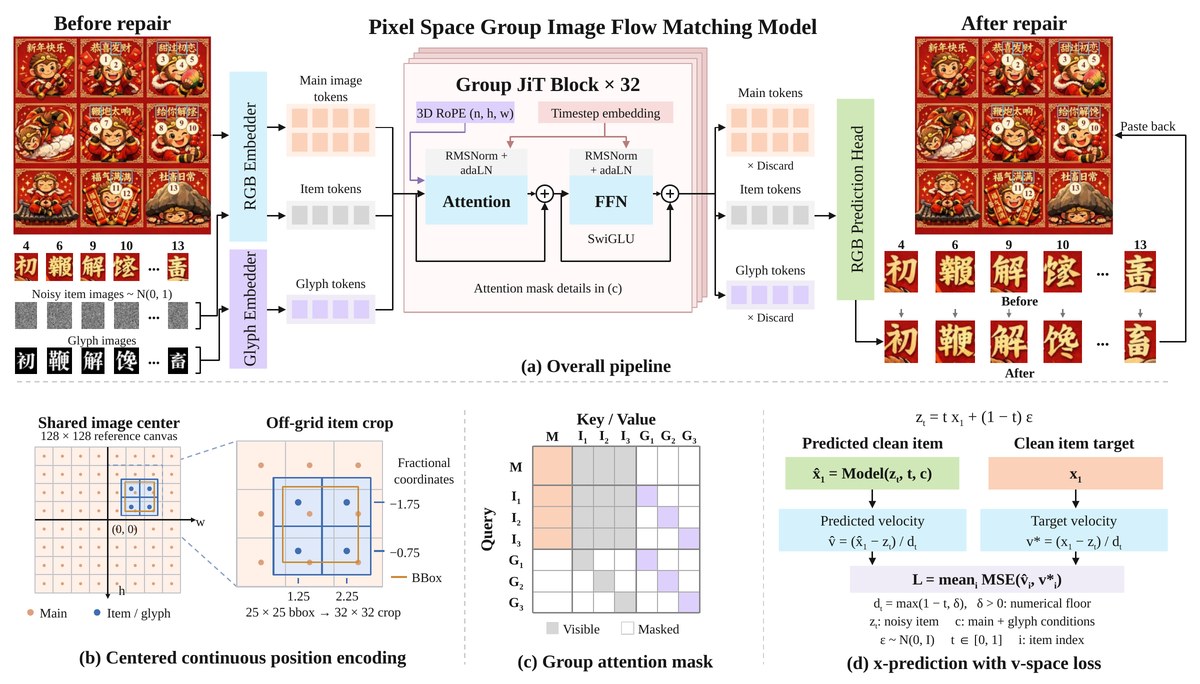
A four-panel diagram of a pixel-space grouped flow-matching transformer for local image repair. It is an editable PowerPoint diagram adapted from the original paper figure under CC BY 4.0.
What the diagram shows
(a) Overall pipeline: before/after images, RGB and glyph embedders, main / item / glyph token groups, a stacked Group JiT Block ×32 (3D RoPE, timestep embedding, RMSNorm + adaLN, Attention, SwiGLU FFN) and an RGB prediction head with paste-back. (b) Centered continuous position encoding on a shared canvas with an off-grid crop. (c) Group attention mask (query × key/value grid). (d) x-prediction with a v-space MSE loss. Every box, arrow, label and math term is a native shape you can recolor, resize and relabel for your own slides, posters or papers.
File format
The download contains .pptx (1 slide, 13.33 × 7.60 in; opens in PowerPoint, Keynote, WPS and LibreOffice Impress; Google Slides works too, but complex freeforms may shift slightly), .svg and .drawio. Includes preview.png (full resolution) and a 1200 px web preview.
Shapes and editing
The file has 368 native editable shapes: 201 auto-shapes, 77 text boxes, 90 freeforms, 0 lines/connectors. 27 embedded images (see below). You can edit all text and formulas (z_t, x̂₁, v̂, v*, d_t, I₁…G₃), the stacked block cards, token grids, embedder bars, position-encoding grid with dots and bounding boxes, the 7×7 mask matrix, loss boxes and arrows.
Embedded images and fonts
27 items are embedded images: the before/after poster grids and the small glyph / noisy-item / character tiles. Text uses Times New Roman, which is preinstalled on Windows and macOS (LibreOffice uses the metric-compatible Liberation Serif). Sub- and superscripts are real formatted text runs, not equation objects. The SVG keeps text as text; the draw.io file is a shape-by-shape conversion and may need small nudges. This is a faithful redraw for reuse, not the authors' original source file.
Source & license Adapted from Figure 1 of Efficient Scene-Text Refinement via Pixel-Space Grouped Image Generation by Yaoli Liu, Guo-Hua Wang, Yiyang Chen, Qing-Guo Chen, Zhao Xu, Weihua Luo, Yao-Xiang Ding (arXiv:2610.18284, https://arxiv.org/abs/2610.18284). Licensed under CC BY 4.0 (https://creativecommons.org/licenses/by/4.0/). Redrawn as editable shapes; changes made by 叫我Alonzo就好了/alonzolab. Not endorsed by the original authors. Attribution to the original paper is required when you publish or share the figure; the exact credit line is in LICENSE-ATTRIBUTION.txt inside each download.