Long-Video VLM Probe-and-Focus Inference Diagram
Overview
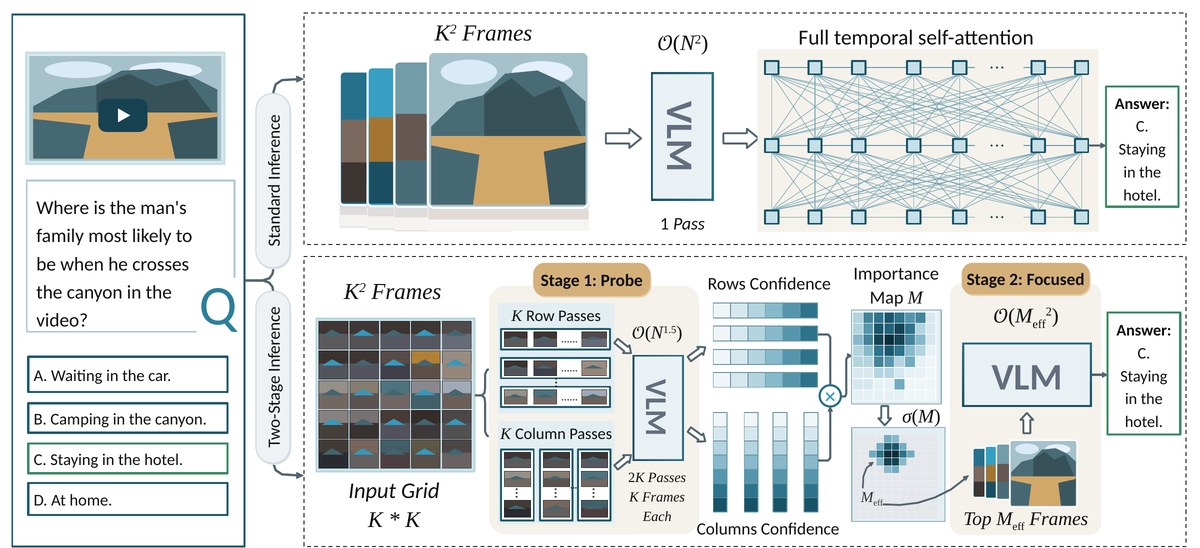
A side-by-side diagram of standard vs two-stage test-time inference for a long-video vision-language model. It is an editable PowerPoint diagram adapted from the original paper figure under CC BY 4.0.
What the diagram shows
Left: a video thumbnail, a multiple-choice question card (A–D) and a large Q branching into two pills. Standard inference: K2 frames (a fanned frame stack) → a VLM at 𝒪(N2), 1 pass → a full temporal self-attention lattice of nodes with all-to-all links → the answer card. Two-stage inference: the K2 frames arranged as a K * K input grid → Stage 1: Probe, with K row passes and K column passes (2K passes, K frames each) through a VLM at 𝒪(N1.5) → rows-confidence and columns-confidence bars, multiplied (⊗) into an importance map M and the masked map σ(M) with the selected Meff cells → Stage 2: Focused, one VLM pass at 𝒪(M2eff) over the top Meff frames → the answer card. Every box, arrow, label and math term is a native shape you can recolor, resize and relabel for your own slides, posters or papers.
File format
The download contains .pptx (1 slide, 16.00 × 7.30 in; opens in PowerPoint, Keynote, WPS and LibreOffice Impress; Google Slides works too, but complex freeforms may shift slightly), .svg and .drawio. Includes preview.png (full resolution) and a 1200 px web preview.
Shapes and editing
The file has 668 native editable shapes: 437 auto-shapes, 42 text boxes, 189 freeforms, 0 lines/connectors (22 small groups). No embedded images. Everything is vector. You can edit all text and math (K2, K * K, 𝒪(N2), 𝒪(N1.5), 𝒪(M2eff), M, σ(M), Meff), the question and option cards, the inference pills and branching connectors, the gradient-bordered VLM boxes, every node and link of the self-attention lattice, the row / column pass strips, every cell of the confidence bars, the importance map and the masked map, the ⊗ node, the hollow arrows, the stage badges and panels, the answer cards and the placeholder video frames.
Embedded images and fonts
This file has no embedded images; everything is vector. Every video frame (the thumbnail, the fanned frame stacks, the input grid and the frames inside the probe strips) is a simplified flat vector placeholder of sky, ridge and ground blocks with no people in it, not the paper's video frames; paste your own frames over them if you need real samples. Body text uses Calibri and formulas use Times New Roman. Calibri ships with Microsoft Office and Times New Roman is preinstalled on Windows and macOS (LibreOffice substitutes the metric-compatible Carlito and Liberation Serif). The script 𝒪 uses Cambria Math, which ships with Microsoft Office; other apps substitute a math font. Sub- and superscripts are real formatted text runs, not equation objects. The SVG keeps text as text; the draw.io file is a shape-by-shape conversion and may need small nudges. This is a faithful redraw for reuse, not the authors' original source file.
Source & license Adapted from Figure 2 of GridProbe: Posterior-Probing for Adaptive Test-Time Compute in Long-Video VLMs by Mohamed Eltahir, Lama Ayash, Ali Habibullah, Tanveer Hussain, Naeemullah Khan (arXiv:2605.10762, https://arxiv.org/abs/2605.10762). Licensed under CC BY 4.0 (https://creativecommons.org/licenses/by/4.0/). Redrawn as editable shapes; changes made by 叫我Alonzo就好了/alonzolab. Not endorsed by the original authors.
Questions or feedback? Email [email protected]