Sparse MoE Expert-Credit Loss Reweighting Diagram
Overview
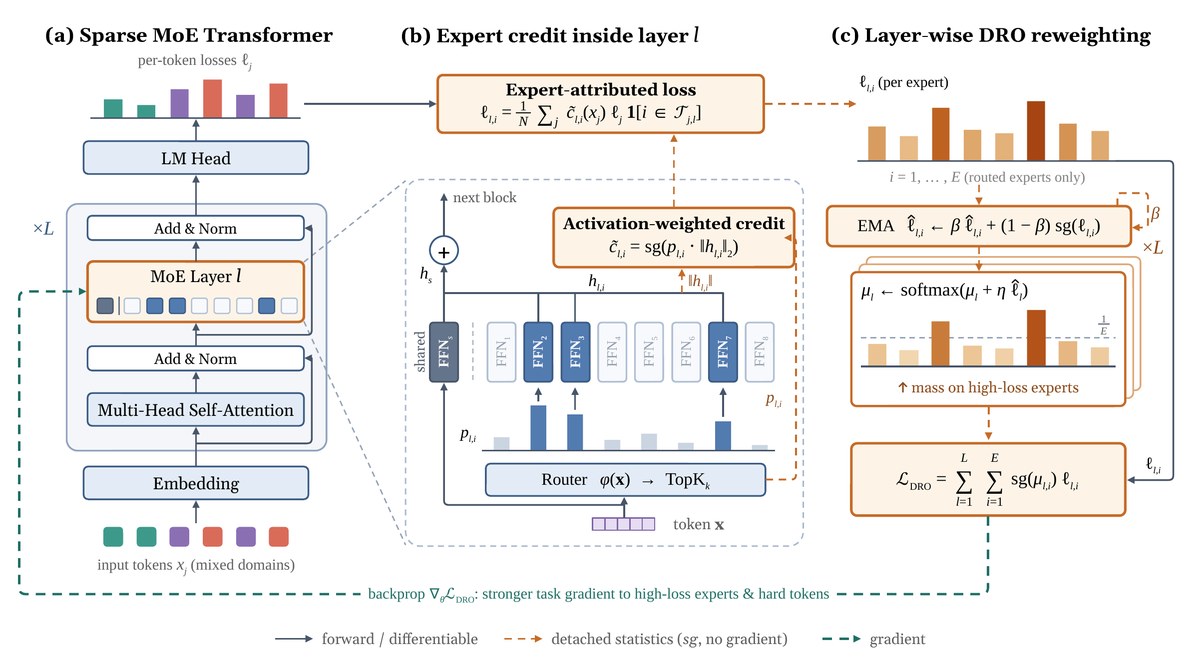
A three-panel diagram of robust training for a sparse mixture-of-experts language model. It is an editable PowerPoint diagram adapted from the original paper figure under CC BY 4.0.
What the diagram shows
(a) Sparse MoE Transformer: mixed-domain input tokens xj → embedding → multi-head self-attention → Add & Norm → MoE layer l → Add & Norm (×L) → LM head → per-token losses ℓj. (b) Expert credit inside layer l: a token x, router φ(x) → Top-k with gate bars pl,i, a shared expert FFNs plus routed experts FFN1 … FFN8, the activation-weighted credit c̃l,i = sg(pl,i · ‖hl,i‖2) and the expert-attributed loss ℓl,i = (1/N) Σj c̃l,i(xj) ℓj 1[i ∈ 𝒯j,l]. (c) Layer-wise DRO reweighting: per-expert loss bars, an EMA tracker ℓ̂l,i ← βℓ̂l,i + (1 − β) sg(ℓl,i), stacked per-layer weight updates μl ← softmax(μl + ηℓ̂l) against the uniform 1/E line, and the objective ℒDRO = Σl Σi sg(μl,i) ℓl,i, whose gradient flows back to high-loss experts and hard tokens. A legend separates forward, detached-statistics and gradient arrows. Every box, arrow, label and math term is a native shape you can recolor, resize and relabel for your own slides, posters or papers.
File format
The download contains .pptx (1 slide, 13.28 × 7.42 in; opens in PowerPoint, Keynote, WPS and LibreOffice Impress; Google Slides works too, but complex freeforms may shift slightly), .svg and .drawio. Includes preview.png (full resolution) and a 1200 px web preview.
Shapes and editing
The file has 171 native editable shapes: 77 auto-shapes, 47 text boxes, 11 freeforms, 36 lines/connectors. No embedded images. Everything is vector. You can edit all text and math (the stacked 1/N and 1/E fractions, Σ limits, ℓl,i, c̃l,i, ‖hl,i‖2, pl,i, ℓ̂l,i with native vector hats, μl, ℒDRO, ∇θ), every loss, gate and weight bar, the token squares, expert columns, stacked per-layer cards, the dashed zoom-in panel, ⊕ node, self-loop β arrow, the three arrow styles and the legend.
Embedded images and fonts
This file has no embedded images; everything is vector. Body text uses Georgia and formulas use Times New Roman; both are preinstalled on Windows and macOS (LibreOffice substitutes the metric-compatible Gelasio and Liberation Serif). The calligraphic 𝒯 and ℒ use Cambria Math, which ships with Microsoft Office; other apps substitute a math font. The hats on ℓ̂ are small native line shapes placed over the letter, so nudge them if you retype the formula. Sub- and superscripts are real formatted text runs, not equation objects. The SVG keeps text as text; the draw.io file is a shape-by-shape conversion and may need small nudges. This is a faithful redraw for reuse, not the authors' original source file.
Source & license Adapted from Figure 1 of Distributionally Robust Mixture-of-Experts Training by Xin Teng, Muxiao Li, Hongyi Wen (arXiv:2610.07207, https://arxiv.org/abs/2610.07207). Licensed under CC BY 4.0 (https://creativecommons.org/licenses/by/4.0/). Redrawn as editable shapes; changes made by 叫我Alonzo就好了/alonzolab. Not endorsed by the original authors.
Questions or feedback? Email [email protected]