Video LLM Architecture Diagram (Editable PowerPoint)
Overview
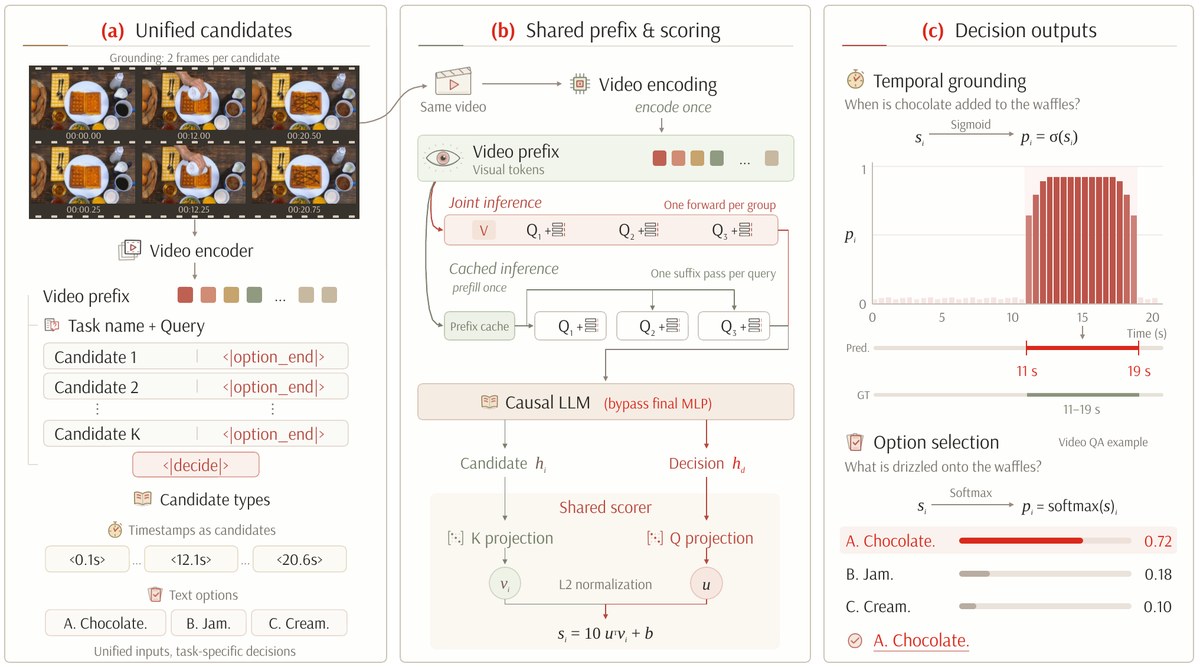
This editable PowerPoint diagram shows a video LLM that scores answer candidates over a shared video prefix, with temporal grounding and option selection. It is adapted from the original paper figure under CC BY 4.0.
What the diagram shows
The figure has three panels. The first shows unified temporal and text candidates. The second compares Cached and Joint inference over a shared video prefix with a shared scorer. The third shows the temporal-grounding and option-selection outputs. Nearly everything, including the panels, boxes, arrows, text, bar charts and timelines, is a native shape you can restyle for your own slides, posters or papers.
File format
The download is a single-slide .pptx file measuring 13.55 × 7.53 in. It opens in PowerPoint, Keynote, WPS and LibreOffice Impress. Google Slides works too, although small layout shifts are possible. A full-resolution preview.png and a 1200 px web preview are included.
Shapes and editing
The file contains 321 shapes in total. 295 of them are native editable shapes (158 auto-shapes, 94 text boxes, 35 lines or connectors and 8 freeforms), and 26 are small embedded raster images. You can edit all text, colors and strokes, as well as the candidate boxes, token blocks, the probability bar chart, the Pred./GT timeline and the option-score bars.
Embedded images and fonts
The 6 video frames (the waffle example in panel a) and 20 small icons (video encoder, clipboard, stopwatch, eye, chip, Q/K projection marks and others) are embedded PNG images. You can move, resize, crop or delete them, but you can't recolor or reshape them like vector shapes. The text uses the fonts "Arsenal" and "Liberation Serif". If they're missing, your app will substitute similar fonts and some labels may need small tweaks. This is a faithful redraw for reuse, not the authors' original source file.
Source & license Adapted from Figure 2 of VideoJev: System One Model for Video Understanding and Interaction by Yuhan Zhu, Xiangyu Zeng, Qingyi Si, Chenxu Yang, Yifei Li, Luozheng Qin, Junhao Zhou, Dingyu Yao, Jun Zhang, Chuanyu Qin, Zhiqiu Zhang, Yuandong Yang, Yuqi Xu, Tianyu Zhang, Hongcheng Guo, Jiaqi Wang, Nan Duan, Limin Wang (arXiv:2610.18615, https://arxiv.org/abs/2610.18615; code: https://github.com/MCG-NJU/VideoJev). The original is licensed under CC BY 4.0 (https://creativecommons.org/licenses/by/4.0/). Converted to editable PowerPoint shapes; changes made by 叫我Alonzo就好了/alonzolab. Not endorsed by the original authors. Please keep the attribution (see LICENSE-ATTRIBUTION.txt) when you reuse the figure.