Video Matting Diffusion Transformer Diagram
Overview
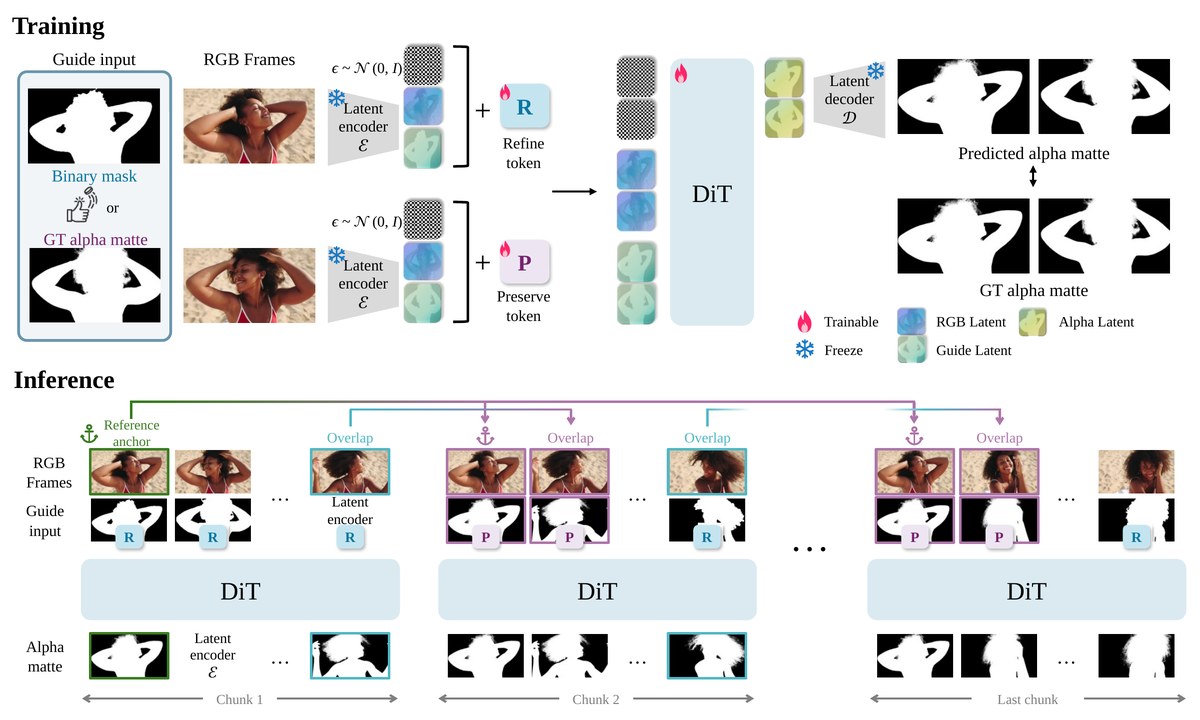
A two-part diagram of a video-matting diffusion transformer. It is an editable PowerPoint diagram adapted from the original paper figure under CC BY 4.0.
What the diagram shows
The Training row shows guide input (binary mask or GT alpha matte) and RGB frames passing through a frozen latent encoder, noise latents, trainable Refine/Preserve tokens, a DiT and a frozen latent decoder, with predicted vs. ground-truth alpha mattes. The Inference row shows chunk-by-chunk processing with reference-anchor and overlap routing across chunks. Every box, arrow, label and math term is a native shape you can recolor, resize and relabel for your own slides, posters or papers.
File format
The download contains .pptx (1 slide, 13.33 × 8.00 in; opens in PowerPoint, Keynote, WPS and LibreOffice Impress; Google Slides works too, but complex freeforms may shift slightly), .svg and .drawio. Includes preview.png (full resolution) and a 1200 px web preview.
Shapes and editing
The file has 96 native editable shapes: 23 auto-shapes, 40 text boxes, 18 freeforms, 15 lines/connectors (4 small groups). 51 embedded images (see below). You can edit all labels and math (ε ∼ 𝒩(0, I), ℰ, 𝒟), panel frames, DiT blocks, encoder/decoder trapezoids, R/P token badges, brackets, routing arrows, chunk arrows, and native flame / snowflake / anchor icons.
Embedded images and fonts
51 items are embedded images: the RGB frames, alpha/guide mattes, the colored latent tiles and the small hand-gesture icon. They come from the source figure at its resolution, so swap in your own frames for large prints. Text uses Times New Roman, which is preinstalled on Windows and macOS (LibreOffice uses the metric-compatible Liberation Serif). A few calligraphic math letters (such as 𝒩, ℰ, 𝒮) use Cambria Math, which ships with Microsoft Office; other apps substitute a math font. Sub- and superscripts are real formatted text runs, not equation objects. The SVG keeps text as text; the draw.io file is a shape-by-shape conversion and may need small nudges. This is a faithful redraw for reuse, not the authors' original source file.
Source & license Adapted from Figure 2 of VideoMaMa++: Temporally Consistent Video Matting via Preserve-and-Refine Token by Sangbeom Lim, Seoung Wug Oh, Heeji Yoon, Seungryong Kim, Joon-Young Lee (arXiv:2610.26857, https://arxiv.org/abs/2610.26857; code: https://github.com/cvlab-kaist/VideoMaMa-PlusPlus). Licensed under CC BY 4.0 (https://creativecommons.org/licenses/by/4.0/). Redrawn as editable shapes; changes made by 叫我Alonzo就好了/alonzolab. Not endorsed by the original authors. Attribution to the original paper is required when you publish or share the figure; the exact credit line is in LICENSE-ATTRIBUTION.txt inside each download.