Video Overlay Removal Flow-Matching Diagram
Overview
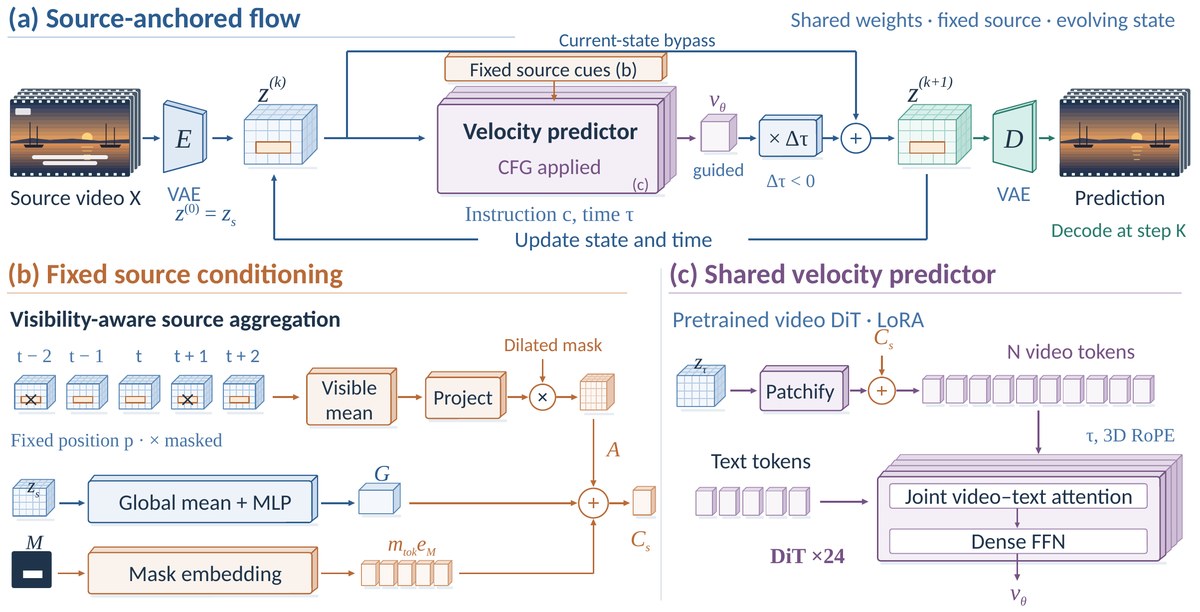
A three-panel diagram of a flow-matching video model that removes on-screen overlays such as subtitles. It is an editable PowerPoint diagram adapted from the original paper figure under CC BY 4.0.
What the diagram shows
(a) Flow loop: source video X → VAE encoder E → latent z(0) = zs → state z(k) → velocity predictor (fixed source cues, CFG, instruction c, time τ) → guided vθ → × Δτ (Δτ < 0) → ⊕ with a current-state bypass → z(k+1), looped by "update state and time", then VAE decoder D → prediction at step K. (b) Fixed source conditioning: visibility-aware aggregation over frames t − 2 … t + 2 (masked frames crossed out) → visible mean → project → × dilated mask → A; zs → global mean + MLP → G; mask M → mask embedding → mtok eM; summed into the source condition Cs. (c) Shared velocity predictor: zτ → patchify → ⊕ Cs → N video tokens plus text tokens → a stacked DiT block (joint video–text attention, dense FFN, τ and 3D RoPE, ×24) → vθ. Every box, arrow, label and math term is a native shape you can recolor, resize and relabel for your own slides, posters or papers.
File format
The download contains .pptx (1 slide, 13.52 × 6.89 in; opens in PowerPoint, Keynote, WPS and LibreOffice Impress; Google Slides works too, but complex freeforms may shift slightly), .svg and .drawio. Includes preview.png (full resolution) and a 1200 px web preview.
Shapes and editing
The file has 812 native editable shapes: 323 auto-shapes, 54 text boxes, 151 freeforms, 284 lines/connectors (2 small groups). No embedded images. Everything is vector. You can edit all text and math (z(0) = zs, z(k), z(k+1), vθ, Δτ, zτ, Cs, A, G, mtok eM), the 3D latent grid cubes with masked-region marks, film-strip frames, the encoder / decoder trapezoids, stacked velocity-predictor and DiT cards, token-cube rows, ⊕ / ⊗ nodes, panel headings and every routed connector.
Embedded images and fonts
This file has no embedded images; everything is vector. The source-video and prediction frames inside the film-strip frames are simplified vector placeholder scenes (the source frame carries generic white overlay bars instead of real subtitles); paste your own frames over them if you need real footage. Body text uses Calibri and formulas use Times New Roman. Calibri ships with Microsoft Office and Times New Roman is preinstalled on Windows and macOS (LibreOffice substitutes the metric-compatible Carlito and Liberation Serif). Sub- and superscripts are real formatted text runs, not equation objects. The SVG keeps text as text; the draw.io file is a shape-by-shape conversion and may need small nudges. This is a faithful redraw for reuse, not the authors' original source file.
Source & license Adapted from Figure 3 of DeOverlay: A Benchmark and Source-Anchored Flow for Video Overlay Removal by Deshui Miao, Yuhang Ma, Shaoyong Jia, Wenzhao Gao, Yue Zhang, Shaohui Jiao, Xin Li (arXiv:2610.26081, https://arxiv.org/abs/2610.26081). Licensed under CC BY 4.0 (https://creativecommons.org/licenses/by/4.0/). Redrawn as editable shapes; changes made by 叫我Alonzo就好了/alonzolab. Not endorsed by the original authors.
Questions or feedback? Email [email protected]