Dual-View World-Model Diffusion Transformer Diagram (Editable PowerPoint)
Overview
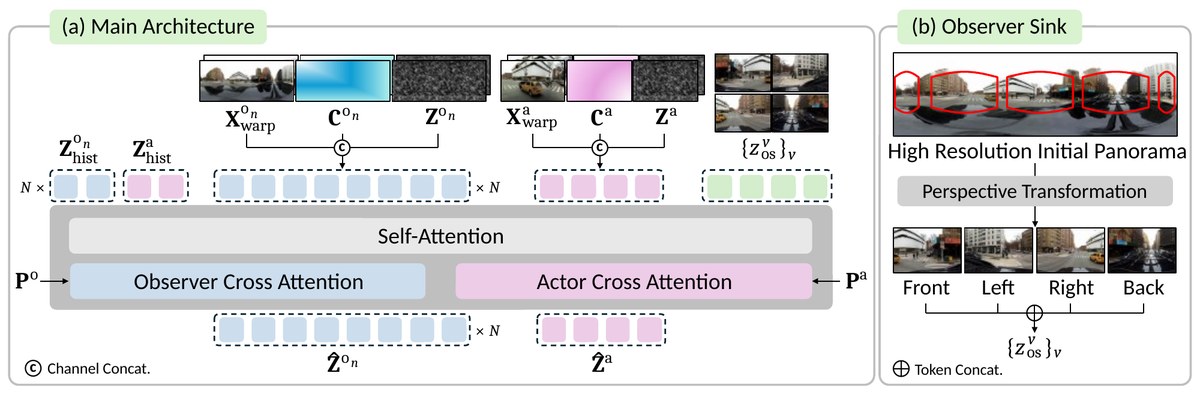
This editable PowerPoint diagram shows a joint two-view (actor and observer) video diffusion transformer for persistent world modeling. It is adapted from the original paper figure under CC BY 4.0.
What the diagram shows
Panel (a) shows warped frames, condition maps and noisy latents fused by channel concatenation into blue and pink token sequences, plus history tokens and green sink tokens. These feed a shared block with Self-Attention and separate Observer and Actor Cross-Attention driven by camera poses Po and Pa, producing denoised outputs Ẑ. Panel (b) shows a high-resolution panorama going through a perspective transformation into Front, Left, Right and Back views, which are then concatenated into sink tokens. The panels, attention blocks, token cells, dashed token groups, connectors, ⓒ/⊕ operators and math labels are native shapes, ready to restyle for your own slides, posters or papers.
File format
The download is a single-slide .pptx file measuring 11.11 × 3.65 in. It opens in PowerPoint, Keynote, WPS and LibreOffice Impress. Google Slides works too, although small layout shifts are possible. A full-resolution preview.png and a 1200 px web preview are included.
Shapes and editing
The file has 167 elements in total: 146 native editable shapes (53 auto-shapes, 69 text boxes, 19 lines or connectors and 5 freeforms) and 21 embedded raster images. Math labels are grouped, so each one moves as a unit. You can edit all text and math labels (Zhist, Xwarp, C, Z, P, Ẑ, {zvos}v), the panel frames and tab labels, the attention blocks, every token cell and dashed group, the concat operators, the arrows and the red field-of-view outlines on the panorama.
Embedded images and fonts
The 21 embedded PNG images are the 12 stacked thumbnails in panel (a) (warped frames, the cyan and pink condition maps and the noise latents, each split into a front and a back card), the 2×2 sink-view thumbnails, the 4 perspective views and the panorama in panel (b). The panorama's red outlines were removed from the pixels and redrawn as native freeform shapes on top. The PNGs are at the source figure's resolution (small thumbnails, roughly 100 px per inch), so swap in your own images for large prints. The text uses Calibri for labels and Cambria for math, and a couple of hat accents use DejaVu Serif. Missing fonts are substituted, and some math labels may need small nudges. Math sub- and superscripts are positioned text boxes and runs, not equation objects. This is a faithful redraw for reuse, not the authors' original source file.
Source & license Adapted from Figure 4 of World Observer: Joint Actor-Observer Generation for Persistent World Modeling by Hyunwook Choi, Dahyun Chung, Hyunsung Kim, Siyoon Jin, Jinhyeok Choi, Junyoung Seo, Seungryong Kim (arXiv:2610.02162, https://arxiv.org/abs/2610.02162; code: https://github.com/cvlab-kaist/world-observer). The original is licensed under CC BY 4.0 (https://creativecommons.org/licenses/by/4.0/). Converted to editable PowerPoint shapes; changes made by 叫我Alonzo就好了/alonzolab. Not endorsed by the original authors. Please keep the attribution (see LICENSE-ATTRIBUTION.txt) when you reuse the figure.