Long-Context Sparse Attention KV-Cache Diagram
Overview
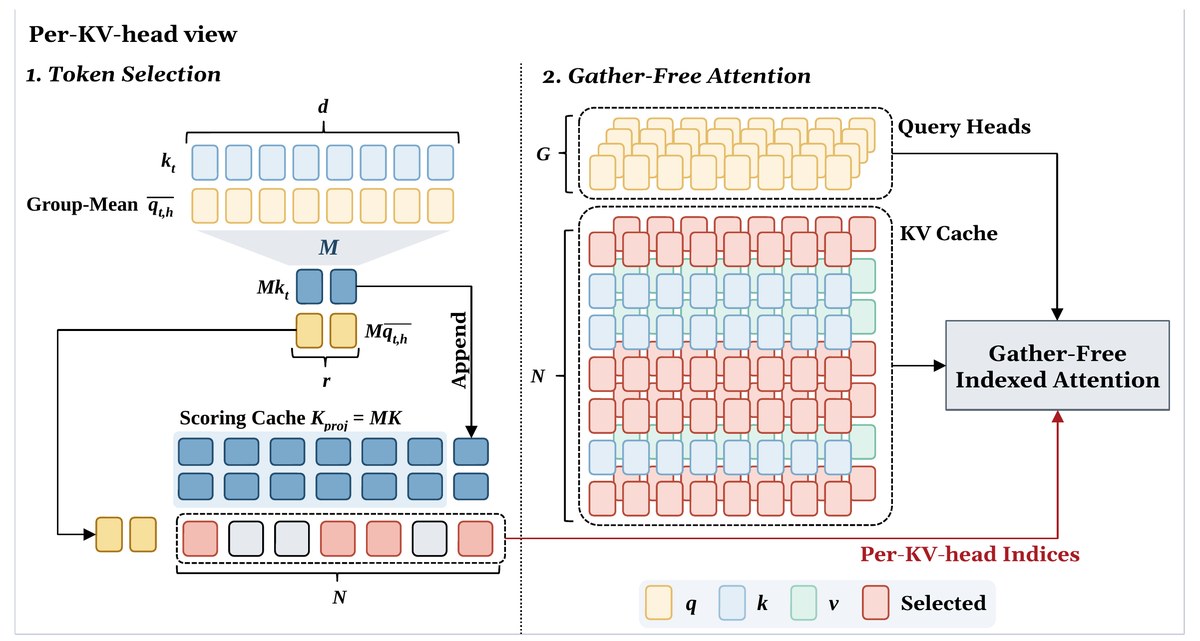
A two-part per-KV-head diagram of sparse attention for long-context decoding. It is an editable PowerPoint diagram adapted from the original paper figure under CC BY 4.0.
What the diagram shows
- Token selection: the new key kt and the group-mean query q̄t,h (width d) are projected by M down to rank r (M kt, M q̄t,h); M kt is appended to a scoring cache Kproj = M K, the projected query scores all N cached tokens, and the top tokens are marked as selected. 2. Gather-free attention: a stack of G query heads and the full KV cache (N rows of interleaved k / v tiles with the selected rows highlighted) feed a gather-free indexed attention block, driven directly by the per-KV-head indices. A legend marks q, k, v and selected tiles. Every box, arrow, label and math term is a native shape you can recolor, resize and relabel for your own slides, posters or papers.
File format
The download contains .pptx (1 slide, 13.28 × 7.09 in; opens in PowerPoint, Keynote, WPS and LibreOffice Impress; Google Slides works too, but complex freeforms may shift slightly), .svg and .drawio. Includes preview.png (full resolution) and a 1200 px web preview.
Shapes and editing
The file has 242 native editable shapes: 203 auto-shapes, 23 text boxes, 0 freeforms, 16 lines/connectors. No embedded images. Everything is vector. You can edit all text and math (kt, q̄t,h with a native overline, M kt, M q̄t,h, Kproj = M K, d, r, N, G), every rounded token tile in the key / query rows, the projection funnel, the scoring cache and selection row, the stacked query-head and KV-cache tile arrays, curly braces, dashed group outlines, the attention block, the red index route and the legend.
Embedded images and fonts
This file has no embedded images; everything is vector. Body text uses Georgia and formulas use Times New Roman; both are preinstalled on Windows and macOS (LibreOffice substitutes the metric-compatible Gelasio and Liberation Serif). Sub- and superscripts are real formatted text runs, not equation objects. The SVG keeps text as text; the draw.io file is a shape-by-shape conversion and may need small nudges. This is a faithful redraw for reuse, not the authors' original source file.
Source & license Adapted from Figure 1 of Joint Subspace Sparse Attention for Efficient Long-Context Decoding by Jiwon Song, Yoongon Kim, Jae-Joon Kim (arXiv:2610.19026, https://arxiv.org/abs/2610.19026). Licensed under CC BY 4.0 (https://creativecommons.org/licenses/by/4.0/). Redrawn as editable shapes; changes made by 叫我Alonzo就好了/alonzolab. Not endorsed by the original authors.
Questions or feedback? Email [email protected]